Earlier work · Data Engineering
Data-Triggered Workflow in Apache Oozie
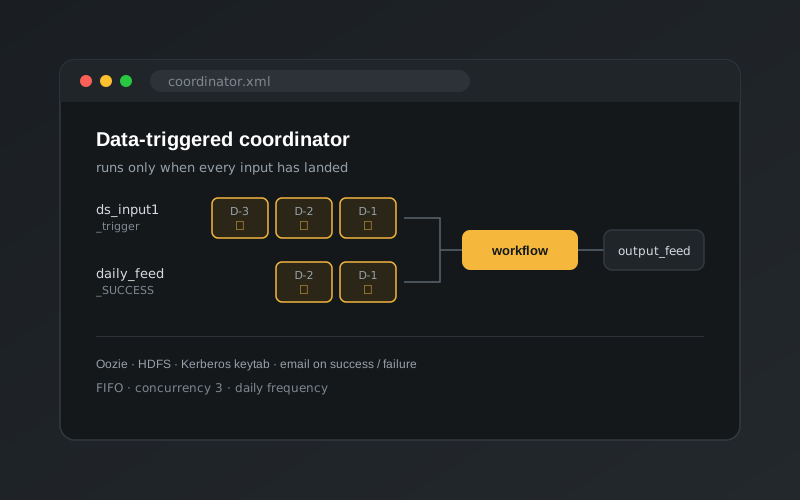
An Oozie coordinator that starts the daily workflow only after three days of one feed and two days of another have fully landed.
The problem
A daily batch job is usually scheduled by time: “run at 2 AM”. But if an upstream feed arrives late or only partly, a time-triggered job runs anyway, on incomplete data, and silently produces wrong output.
This project schedules the job by data availability instead. Apache Oozie only starts each day’s run once all the input data it depends on has landed.
The rule
Each daily run depends on two input datasets in HDFS, stored in date-partitioned folders (.../YYYY-MM-DD):
| Input | Must be complete for |
|---|---|
ds_input1 |
the previous 3 days |
daily_feed |
the previous 2 days |
If any of those five daily folders is missing or incomplete, Oozie waits. As soon as the last one arrives, the run starts, and it writes to that day’s output_feed folder.
How it’s built
Coordinator (coordinator.xml)
- Datasets. Each input is declared as a daily dataset with a URI template like
/user/<user>/ds_input1/${YEAR}-${MONTH}-${DAY}. - Done flags. A folder only counts as complete once a marker file exists.
ds_input1uses a custom_triggerfile, anddaily_feeduses Hadoop’s default_SUCCESSfile. This avoids picking up a folder that is still being written. - Input windows.
coord:current(-3)tocurrent(-1)andcurrent(-2)tocurrent(-1)express “the last three days” and “the last two days” relative to each run’s date. - Controls. Runs execute in FIFO order with up to 3 running at once, so a backlog clears in date order after an outage.
- Parameters passed to the workflow: the run date, offsets such as the previous month and two days back, the exact input folders that satisfied the dependency, and the output folder.
Workflow (workflow.xml)
- A shell action runs the processing script. It receives every coordinator parameter and authenticates to the Kerberos-secured cluster with a keytab, so it can query Hive and Impala.
- On success an email action sends a success notice. On any failure an email alert goes out and the workflow is killed, so failures are never silent.
- A Hive2 action is also sketched out (commented out) for future SQL steps.
Deployment scripts
bin/run_workflow.shvalidates the workflow XML, uploads it to HDFS with the keytab, and runs it once, which is useful for testing.bin/stage_coordinator.shvalidates the coordinator, uploads everything, sets HDFS permissions on the input and output folders, and stages the recurring schedule fromcoordinator.properties.
Why it matters
Data-triggered scheduling makes a pipeline correct by construction: output for a day is only produced from complete inputs, late data simply delays the run instead of corrupting it, and a missed day is replayed automatically once its data appears.